Skip to content

Instantly share code, notes, and snippets.

@jboner
jboner / latency.txt
Last active September 27, 2026 20:44
Latency Numbers Every Programmer Should Know
Latency Comparison Numbers (~2012)
----------------------------------
L1 cache reference 0.5 ns
Branch mispredict 5 ns
L2 cache reference 7 ns 14x L1 cache
Mutex lock/unlock 25 ns
Main memory reference 100 ns 20x L2 cache, 200x L1 cache
Compress 1K bytes with Zippy 3,000 ns 3 us
Send 1K bytes over 1 Gbps network 10,000 ns 10 us
Read 4K randomly from SSD* 150,000 ns 150 us ~1GB/sec SSD
@Fuwn
Fuwn / README.md
Last active September 27, 2026 20:39
Windows XP All Editions Universal Product Keys Collection

Windows XP Logo

Although Microsoft no longer supports Windows XP updates, I'm sure many users still use it due to personal habits or job demands. Therefore, XP's product keys may still be necessary. Here lies the most comprehensive list of Windows XP product keys.

The following CD keys are official and original from Microsoft, primarily used for Windows XP Professional Service Pack 2/3 VOL/VLK system images, which are among the easiest to find on the Internet.
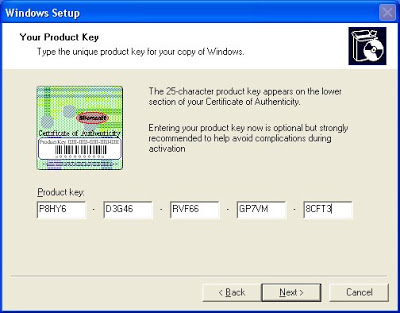
Windows XP Setup

Windows XP Professional 32-bit Edition

@k16shikano
k16shikano / SKILL.md
Last active September 27, 2026 20:34
cognitive-rhythm-writing/SKILL.md
name cognitive-rhythm-writing
description 説明的な文章に緩急を設計するための規範。緩急を装飾ではなく認知モードの切替(観察→逡巡→断定→再観察)と未回収の緊張の管理として扱い、文の拍、段落の密度波形、節の入り方、緩みと駄文の判別、執筆後の機械的な点検手順を定める。読み物として読ませたい章・記事・解説文を生成するとき、または「密度はあるが平坦でおもしろくない」文章を診断・修正するときに使用する。

認知リズムを生むための日本語ライティング規範

密度の高い文章が退屈になるのは、情報が多いからではなく、全文が同じ認知モードで書かれているからである。 この規範は、読者の認知モード(観察する、迷う、確信する、確かめ直す)を意図的に切り替え、常に「続きを読む理由」を維持することで、読み進める推進力を作る。

LLM Wiki

A pattern for building personal knowledge bases using LLMs.

This is an idea file, it is designed to be copy pasted to your own LLM Agent (e.g. OpenAI Codex, Claude Code, OpenCode / Pi, or etc.). Its goal is to communicate the high level idea, but your agent will build out the specifics in collaboration with you.

The core idea

Most people's experience with LLMs and documents looks like RAG: you upload a collection of files, the LLM retrieves relevant chunks at query time, and generates an answer. This works, but the LLM is rediscovering knowledge from scratch on every question. There's no accumulation. Ask a subtle question that requires synthesizing five documents, and the LLM has to find and piece together the relevant fragments every time. Nothing is built up. NotebookLM, ChatGPT file uploads, and most RAG systems work this way.

@tuxtor
tuxtor / Fixing-terminals.md
Created May 20, 2023 13:19
Fixing 'unknown terminal type' error for newer terminals

In order to fix this small bug, you should install terminal info on the DESTINATION machine (the one you are probably reaching through ssh).

Alacritty

curl -sSL https://raw.githubusercontent.com/alacritty/alacritty/master/extra/alacritty.info | tic -x -

Foot

@akshatgit
akshatgit / README.md
Last active September 27, 2026 20:26
Notes for Meta Production Engineer Intern Systems Round

I have received Production intern offer from FB, and while preparing for it I could not find many resources to prepare for the systems interview round. Hence, I decided to create my own preparation material. If you find any error, feel free to send a PR to improve the notes. I found these questions from this blog and I referred to OS book by Tanenbaum.

There are 2 rounds for PE internship, the first is the coding round and second systems round. In the coding round the questions are of easy to medium leetcode level. In the systems round, the main focus is to check the OS knowledge, with a particular focus on Linux based concepts. The following are the set of questions I had prepared, try to get an in-depth understanding of how and why a process is designed in such a manner.

What happens during the boot process from

@rohitg00
rohitg00 / llm-wiki.md
Last active September 27, 2026 20:25 — forked from karpathy/llm-wiki.md
LLM Wiki v2 — extending Karpathy's LLM Wiki pattern with lessons from building agentmemory

LLM Wiki v2

A pattern for building personal knowledge bases using LLMs. Extended with lessons from building agentmemory 20K+ Stars ⭐️, a persistent memory engine for AI coding agents.

This builds on Andrej Karpathy's original LLM Wiki idea file. Everything in the original still applies. This document adds what we learned running the pattern in production: what breaks at scale, what's missing, and what separates a wiki that stays useful from one that rots.

What the original gets right

The core insight is correct: stop re-deriving, start compiling. RAG retrieves and forgets. A wiki accumulates and compounds. The three-layer architecture (raw sources, wiki, schema) works. The operations (ingest, query, lint) cover the basics. If you haven't read the original, start there.